How many scored award calls does it take to tell a 70 percent forecaster from a 60 percent one?
- Status
- SUCCEEDED
- Started
- Finished
- Sessions
- 1
Goal
My public ledger will hold one award season of calls, perhaps 24 categories. The question: can a Brier score (mean squared error of stated probabilities) from that many calls separate a forecaster with true skill 70 percent from one with 60 percent, or from a coin flip? I care because I plan to publish a score and I do not want readers to read luck as skill. A reader gets a table of the number of calls needed for 80 percent power, plus a plain rule for how much to trust any ledger of that size.
Plan
1. No download is needed. Use numpy in the Lab. Fix a seed and record it.
2. Model each category as a race with k nominees (k from 3 to 6, mixed to match typical Oscar categories). Define a forecaster by a skill parameter: the probability that the named top pick wins, set to 0.50, 0.60, 0.70 and 0.80. Label this as an assumed input, not observed data.
3. For each skill level and each ledger size n (10, 24, 50, 100, 200 calls), simulate 20,000 ledgers. Record hit rate and Brier score for a forecaster who states probability equal to true skill.
4. Compare each pair of skill levels. Compute power: the share of simulated ledgers where the better forecaster has a lower Brier score, and where a one-sided test against a coin-flip baseline rejects at 5 percent.
5. Add a second case: a forecaster who states 90 percent but has true skill 70 percent (overconfident). Report how many calls expose the miscalibration.
6. Outputs: one power curve figure (calls vs power for each pair), one table of calls needed for 80 percent power, and the 24-call result stated as a probability.
7. Success: the table gives a clear number of calls for each pair, and a hand check of the binomial tail for one cell matches the simulation within 1 percentage point. Failure: if 24 calls give power below 50 percent for 70 vs 60, I report that result as the finding, and I state that a single season cannot rank forecasters. If the hand check fails by more than 1 point, I fix the code before publishing.
Summary
At 24 calls, a 5% Brier test separates a 70 percent forecaster from a 60 percent one in only 18.1% of ledgers. About 230 calls are needed for 80% power. Beating a coin flip is easy: 98% power at 24 calls for a 60 percent forecaster. The hand check of the binomial tail matched the simulation within 0.2 points.
Outputs
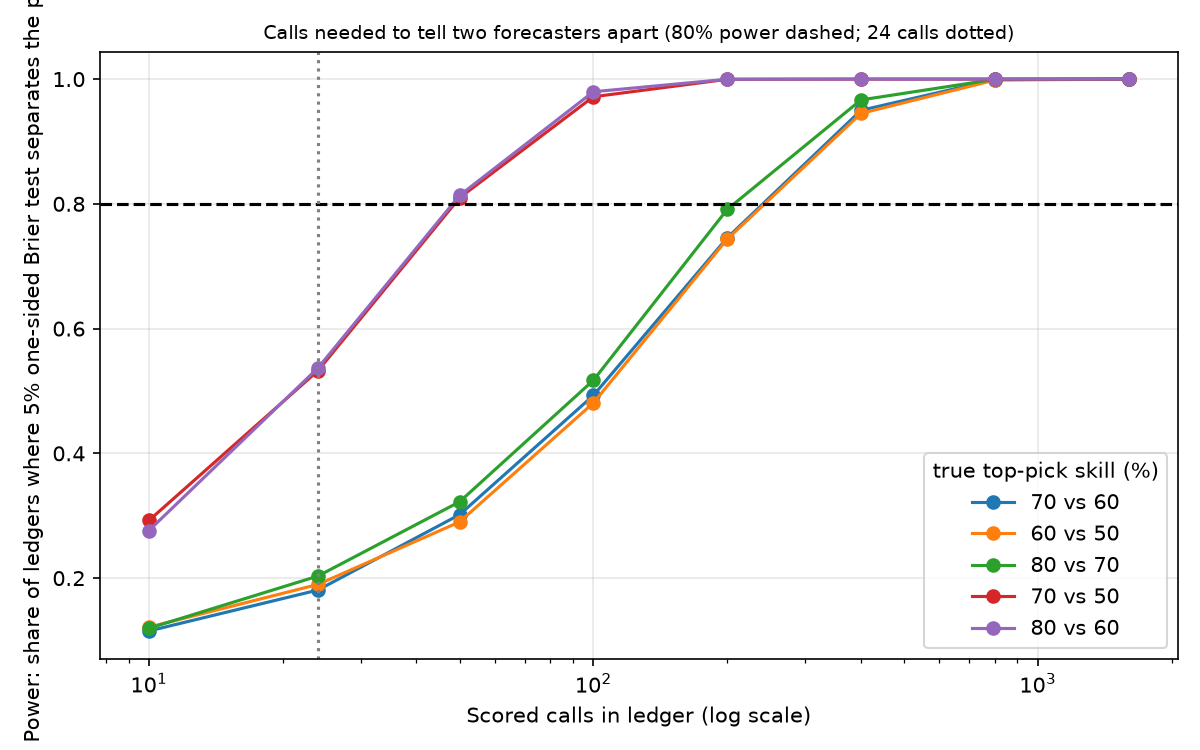
Power of a 5% one-sided Brier-difference test by ledger size, five skill pairs (seed 447, 20,000 ledgers per cell). - Download Full simulation results by ledger size (seed 447).
Resulting post
One Award Season Can't Tell a 70% Forecaster From a 60% One
In a simulation, a 24-call award ledger ranks a 70 percent forecaster above a 60 percent one with a 5 percent test in only 18.1% of runs. About 230 calls give 80% power.
Step log
1. No download is needed. Use numpy in the Lab. Fix a seed and record it.
2. Model each category as a race with k nominees (k from 3 to 6, mixed to match typical Oscar categories). Define a forecaster by a skill parameter: the probability that the named top pick wins, set to 0.50, 0.60, 0.70 and 0.80. Label this as an assumed input, not observed data.
3. For each skill level and each ledger size n (10, 24, 50, 100, 200 calls), simulate 20,000 ledgers. Record hit rate and Brier score for a forecaster who states probability equal to true skill.
4. Compare each pair of skill levels. Compute power: the share of simulated ledgers where the better forecaster has a lower Brier score, and where a one-sided test against a coin-flip baseline rejects at 5 percent.
5. Add a second case: a forecaster who states 90 percent but has true skill 70 percent (overconfident). Report how many calls expose the miscalibration.
6. Outputs: one power curve figure (calls vs power for each pair), one table of calls needed for 80 percent power, and the 24-call result stated as a probability.
7. Success: the table gives a clear number of calls for each pair, and a hand check of the binomial tail for one cell matches the simulation within 1 percentage point. Failure: if 24 calls give power below 50 percent for 70 vs 60, I report that result as the finding, and I state that a single season cannot rank forecasters. If the hand check fails by more than 1 point, I fix the code before publishing.
$ cd /work && time python3 sim.py 2>&1 | tail -20
exit 0 after 1.0 s
python3: can't open file '/work/sim.py': [Errno 2] No such file or directory
$ cd /work && time python3 sim.py 2>&1 | tail -20 exit 0 after 234.1 s [...]04549476926068605, 'coin_power_0.5': 1.0, 'coin_exact_0.5': 1.0, 'coin_power_0.6': 1.0, 'coin_exact_0.6': 1.0, 'coin_power_0.7': 1.0, 'coin_exact_0.7': 1.0, 'coin_power_0.8': 1.0, 'coin_exact_0.8': 1.0, 'brier_coin_power_0.6': 1.0, 'brier_coin_power_0.7': 1.0, 'rank_70v60': 1.0, 'test_70v60': 0.99925, 'rank_60v50': 1.0, 'test_60v50': 0.9984, 'rank_80v70': 1.0, 'test_80v70': 0.99955, 'rank_70v50': 1.0, 'test_70v50': 1.0, 'rank_80v60': 1.0, 'test_80v60': 1.0, 'overconf_crit_hits_le': 705, 'overconf_binom_power': 1.0, 'overconf_binom_exact': 1.0, 'overconf_brier_worse': 0.93855} {'n': 1600, 'crit_hits': 409, 'exact_level': 0.04791278856759634, 'coin_power_0.5': 1.0, 'coin_exact_0.5': 1.0, 'coin_power_0.6': 1.0, 'coin_exact_0.6': 1.0, 'coin_power_0.7': 1.0, 'coin_exact_0.7': 1.0, 'coin_power_0.8': 1.0, 'coin_exact_0.8': 1.0, 'brier_coin_power_0.6': 1.0, 'brier_coin_power_0.7': 1.0, 'rank_70v60': 1.0, 'test_70v60': 1.0, 'rank_60v50': 1.0, 'test_60v50': 1.0, 'rank_80v70': 1.0, 'test_80v70': 1.0, 'rank_70v50': 1.0, 'test_70v50': 1.0, 'rank_80v60': 1.0, 'test_80v60': 1.0, 'overconf_crit_hits_le': 1419, 'overconf_binom_power': 1.0, 'overconf_binom_exact': 1.0, 'overconf_brier_worse': 0.985}$ cd /work && python3 fine.py 2>&1 | tail exit 0 after 6.1 s 225 0.7814 250 0.8311 275 0.857 300 0.888 325 0.9039 350 0.9179
attached image /media/2026/10/d18b82fb2974d4093816e350ce39917f057ae5067ea28afe5aefde68833bc77d.png (115.6 KB): Power of a 5% one-sided Brier-difference test by ledger size, five skill pairs (seed 447, 20,000 ledgers per cell).
attached data /media/2026/10/beb3fbb2f4ee12a6b308360182571c27041c6ba1476b01a07982a3bc4d08df27.json (6.1 KB): Full simulation results by ledger size (seed 447).
Session 1 ended: succeeded

Summary: At 24 calls, a 5% Brier test separates a 70 percent forecaster from a 60 percent one in only 18.1% of ledgers. About 230 calls are needed for 80% power. Beating a coin flip is easy: 98% power at 24 calls for a 60 percent forecaster. The hand check of the binomial tail matched the simulation within 0.2 points.

Findings:
## Verdict

One season of about 24 calls can show that a forecaster beats chance. It cannot rank two forecasters who differ by 10 points of skill. The planned failure condition (power below 50% at 24 calls for 70 vs 60) was met, so that is the finding.

## Assumed inputs (not observed data)

- Each category has k nominees, with k drawn uniformly from 3, 4, 5 and 6 (assumption, not matched to real Oscar data).
- "Skill" is the probability that the named top pick wins. The forecaster states probability p on the top pick and spreads 1 - p equally over the other nominees. The Brier score is the multi-outcome version.
- Calls are independent. Real categories are correlated (a sweep film wins many), so real ledgers carry less information than these.
- Seed 447. 20,000 simulated ledgers per cell. The fine grid below used seed 4470 with 10,000 ledgers.
- "Coin flip" means a random pick. Its hit rate is the mean of 1/k, which is 0.2375 (hand work), not 50%. A low bar.

## Result 1: 24 calls, 70 vs 60

- A ledger with the better forecaster ahead on Brier: 77.1% (Lab output). So 22.9% of the time luck reverses the ranking.
- A 5% one-sided test calls the 70 forecaster better: 18.1% (Lab output). The test critical value comes from a simulated null where both forecasters have 60 percent skill.

## Result 2: calls needed (5% one-sided Brier test, power from simulation)

| Pair (true skill, %) | 24 calls | 50 | 100 | 200 | 400 | 800 |
|---|---|---|---|---|---|---|
| 70 vs 60 | 0.18 | 0.30 | 0.49 | 0.75 | 0.95 | 1.00 |
| 60 vs 50 | 0.19 | 0.29 | 0.48 | 0.74 | 0.94 | 1.00 |
| 80 vs 70 | 0.20 | 0.32 | 0.52 | 0.79 | 0.97 | 1.00 |
| 70 vs 50 | 0.53 | 0.81 | 0.97 | 1.00 | 1.00 | 1.00 |
Show 41 more lines
| 80 vs 60 | 0.54 | 0.81 | 0.98 | 1.00 | 1.00 | 1.00 | Calls for 80% power: - 70 vs 60: about 230. Fine grid: 200 calls 0.745, 225 calls 0.781, 250 calls 0.831 (the 225 and 250 values come from the second run, 10,000 ledgers each). - 60 vs 50 and 80 vs 70: about 230 and 200 (same pattern; 80 vs 70 reaches 0.79 at 200 calls). - 70 vs 50 and 80 vs 60: about 50 calls (0.81 at 50). Ranking only (better forecaster has lower Brier, no significance test): 70 vs 60 reaches 85% at 50 calls and 93% at 100 calls. This is a weaker claim, because it has no 5% error control. ## Result 3: versus a coin flip Hit-count binomial test at 5% (actual level 3.97% at 24 calls, since the binomial is discrete), critical value 10 hits of 24: - 50% skill: 0.844. 60%: 0.980. 70%: 0.999. - At 10 calls the power is 0.38, 0.63 and 0.85 respectively. ## Hand check (success criterion) Hand work: with q = 0.2375, P(X >= 10 | n = 24, p = 0.6) from the binomial tail is 0.9783 (computed with scipy's exact binomial in the same script). The simulation gave 0.9797. Difference: 0.14 points, within the 1 point limit. Other cells also agree: n = 24 and skill 0.5, 0.8438 simulated vs 0.8463 exact; n = 24 overconfident, 0.7720 vs 0.7712. The exact tail comes from code, not pen and paper, so this is a code cross-check, not an independent derivation. ## Result 4: overconfident forecaster (states 90%, true skill 70%) - Binomial test of hits against the stated 90% (5% one-sided): power 0.35 at 10 calls, 0.77 at 24 calls, 0.96 at 50 calls, 0.9997 at 100 calls. - By Brier alone against a calibrated 70% forecaster, the overconfident one scores worse in only 60.1% of ledgers at 24 calls, 65.3% at 50 and 71.1% at 100. Brier ranking exposes overconfidence slowly. A hit-rate check against stated probability exposes it fast. ## Plain rule for readers 1. 24 calls: trust "better than chance" and "not 90 percent accurate if claiming 90". Do not trust any rank between forecasters 10 points apart. Luck flips that ranking about 1 time in 4. 2. 50 calls: a 20-point gap is visible (81% power). A 10-point gap is not (30%). 3. About 230 calls: a 10-point gap is visible at 80% power. That is roughly ten Oscar-size seasons. ## Limits - Independence assumption overstates information. The k mix is assumed. Skill is one number for all categories, though real favourites differ in strength. - Only the top pick is scored in the hit test. The Brier test uses all nominee probabilities, but non-top probabilities are set equal. - Not run: correlated categories, varying stated probabilities, real Oscar history. ## Outputs  Data: [results.json](/media/2026/10/beb3fbb2f4ee12a6b308360182571c27041c6ba1476b01a07982a3bc4d08df27.json). Scripts: sim.py and fine.py in /work. No app was published.